See your fabric live
October 1, 2026 · SpineRail engineering
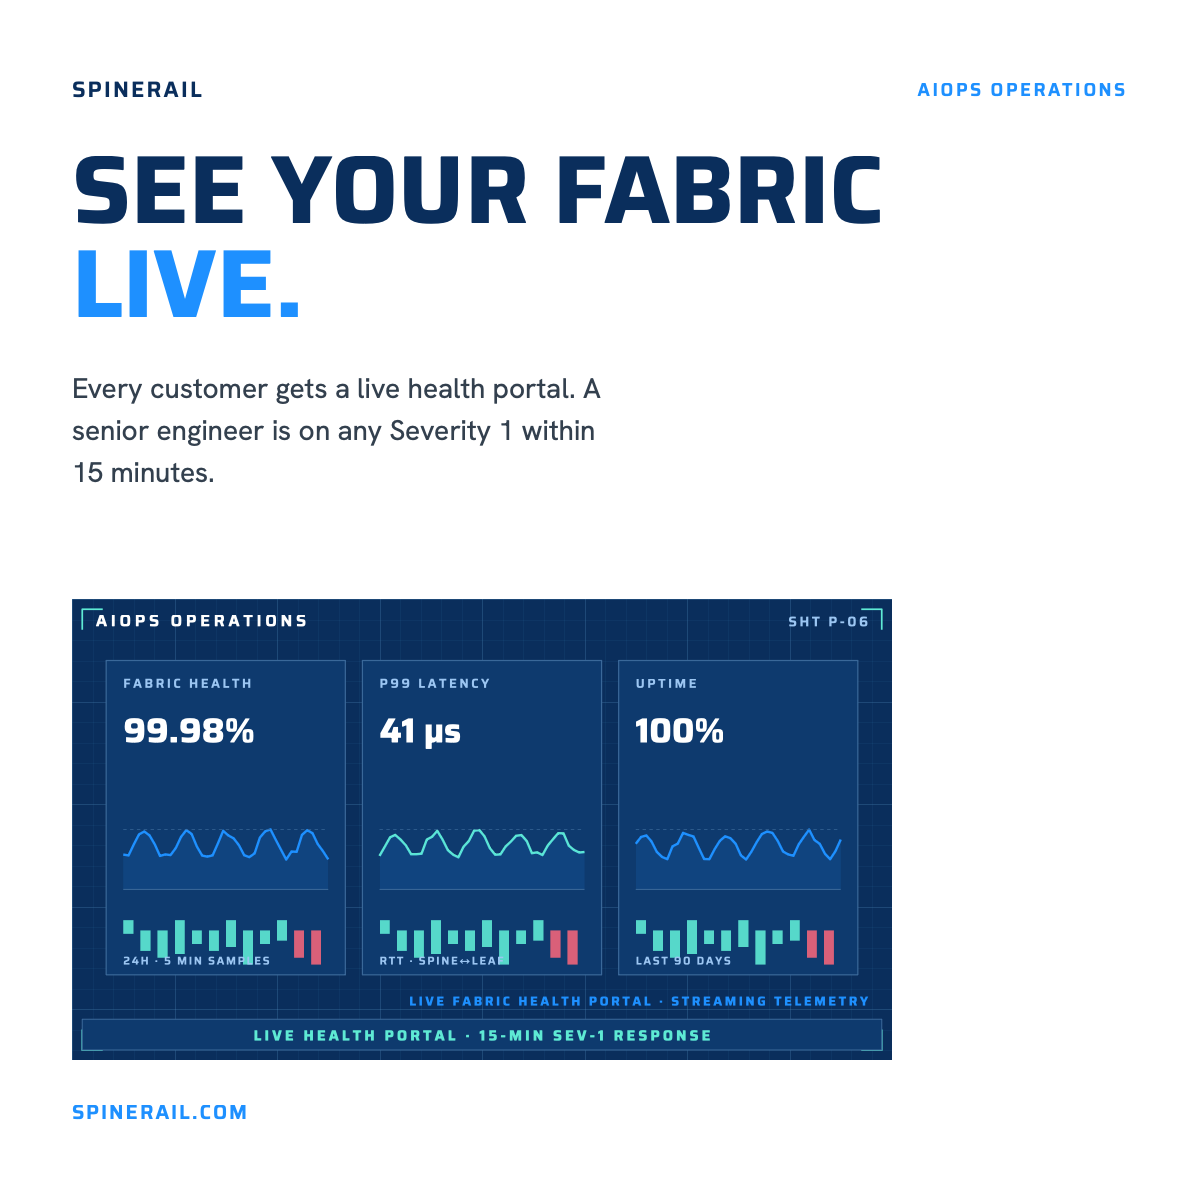
Managed network operations usually means a ticket queue and a monthly report. Ours means a live portal: fabric health, p99 latency between spine and leaf, uptime over 90 days, and the change history, visible to your team at all times.
Behind it is streaming telemetry from every device, Marvis for Juniper Mist campuses, Apstra's intent-based analytics for datacenter fabrics and CloudVision for Arista — watched by engineers who know what the alerts mean and can act on them, as code, through the same twin-validated pipeline used to build the network.
A senior engineer joins any Severity 1 within 15 minutes. Not a dispatcher, not a first-line script: someone who has built fabrics like yours and has the access to fix it.